Cresus Casino mobile : jouez où vous voulez en toute sécurité et rapidement


Cresus Casino est une plateforme de jeu en ligne qui a su gagner la confiance des joueurs français grâce à sa large gamme de jeux et à ses offres attractives. En 2026, l’univers des casinos en ligne devient de plus en plus compétitif, et Cresus Casino se distingue par ses caractéristiques uniques, telles que l’absence d’exigences de mise sur ses bonus. Ce guide vous aidera à explorer les différentes facettes du casino mobile, notamment sur lechatsurtroispattes.com , vous permettant de jouer en toute sécurité et rapidement, où que vous soyez.
Évaluer Cresus Casino sans deviner

Comprendre les éléments essentiels d’un casino en ligne est crucial pour une expérience de jeu satisfaisante. Cresus Casino se démarque par sa fiabilité et la diversité de son offre. Ce casino attire non seulement les nouveaux joueurs, mais aussi les habitués grâce à ses fonctionnalités intéressantes, comme un programme VIP attrayant et un catalogue de jeux diversifié. En analysant des aspects tels que les méthodes de paiement, les bonus et les avis des utilisateurs, vous serez en mesure de vous faire une idée précise de ce que le casino a à offrir.

La sécurité et la réglementation sont également primordiales dans le choix d’un casino en ligne. Cresus Casino garantit un environnement de jeu sécurisé et équitable grâce à des technologies de cryptage avancées et à un engagement envers la transparence.

Comment commencer à jouer sur Cresus Casino

Commencer à jouer sur Cresus Casino est simple et rapide. Suivez ces étapes pour profiter de tout ce que la plateforme a à offrir.

  1. Créer un compte : Rendez-vous sur le site de Cresus Casino et remplissez le formulaire d’inscription.
  2. Vérifier vos informations : Assurez-vous que vos données personnelles sont correctes pour faciliter le processus de vérification.
  3. Effectuer un dépôt : Choisissez parmi plusieurs méthodes de paiement sécurisées pour ajouter des fonds à votre compte.
  4. Sélectionner votre jeu : Parcourez le vaste catalogue de jeux, incluant machines à sous, jeux de table et casino en direct.
  5. Commencer à jouer : Lancez votre première partie et profitez de votre expérience de jeu.
  • Créer un compte est gratuit et rapide.
  • Un processus de vérification simple pour une sécurité accrue.
  • Options de dépôt variées et sécurisées.

Détails pratiques sur Cresus Casino

Le casino en ligne Cresus propose une multitude de jeux adaptés aux goûts variés des joueurs. Que vous soyez fan des machines à sous ou des jeux de table comme le blackjack et la roulette, vous trouverez votre bonheur. En 2026, le casino élargit continuellement son catalogue, ajoutant de nouveaux titres populaires et des fonctionnalités innovantes. De plus, Cresus Casino offre un programme de bonus sans exigences de mise, ce qui signifie que vous pouvez retirer vos gains sans conditions contraignantes.

  • Une large sélection de jeux avec des développeurs de renom.
  • Des bonus attractifs, comme un bonus de bienvenue de 200 % jusqu’à 500 €.
  • Des fonctionnalités de jeu mobile optimisées pour une expérience fluide.

Avec une note de 4,5/5 par les utilisateurs, Cresus Casino est reconnu pour son service client de qualité, garantissant que chaque joueur soit soutenu tout au long de son expérience.

Avantages clés de Cresus Casino

Choisir Cresus Casino, c’est opter pour une expérience de jeu enrichissante avec de nombreux avantages. Non seulement le casino se concentre sur l’expérience utilisateur, mais il propose également plusieurs fonctionnalités qui le distinguent.

  • Programme VIP attractif avec des avantages exclusifs.
  • Pas d’exigences de mise sur les bonus, facilitant le retrait des gains.
  • Une interface intuitive sur mobile, permettant de jouer à tout moment.
  • Des promotions régulières et des tournois pour dynamiser votre expérience de jeu.

Ces aspects font de Cresus Casino un choix incontournable pour les amateurs de jeux en ligne.

Confiance et sécurité

La sécurité est une priorité absolue sur Cresus Casino. Le site utilise des protocoles de sécurité avancés pour protéger vos informations personnelles et financières, garantissant un environnement de jeu sûr. Cresus Casino est licencié et réglementé, ce qui renforce encore sa crédibilité. Les joueurs peuvent donc se concentrer sur le jeu, en sachant que leurs données sont protégées contre toute intrusion.

De plus, un système de support client réactif est mis en place, offrant une assistance rapide en cas de problème, ce qui renforce la confiance des joueurs envers la plateforme.
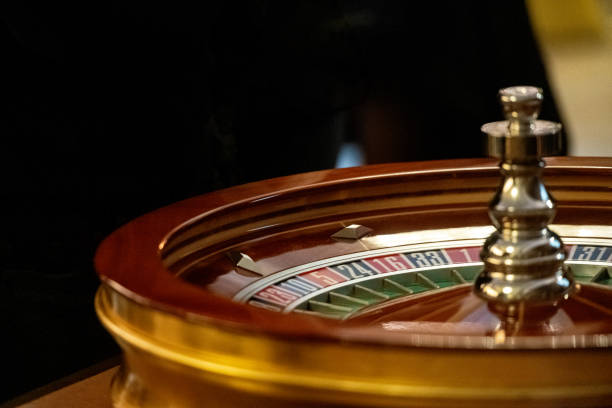
Pourquoi choisir Cresus Casino

En somme, Cresus Casino se présente comme un choix de premier ordre pour les joueurs en ligne en 2026. Avec des offres variées, des bonus sans exigences de mise et une excellente sécurité, cette plateforme s’adapte aux besoins de tous les joueurs. Les avantages supplémentaires tels que son programme VIP et un support client efficace créent une expérience de jeu positive, encourageant les joueurs à revenir.

En choisissant Cresus Casino, vous optez pour une aventure ludique enrichissante pleinement sécurisée, où le plaisir de jouer est à la fois accessible et satisfaisant. N’attendez plus, rejoignez dès maintenant Cresus Casino et découvrez un monde de divertissement à portée de main.

Software reliability check MAGICQA20261109 03156


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when problems occur. This technical guide uses MAGICQA20261109 as a temporary publication test label, not as a product or certification. It explains how beginners can plan practical checks, gather useful evidence, and interpret results without confusing reliability with a guarantee that software will never fail. The focus is on repeatable quality assurance 03156 practices that support informed engineering decisions throughout development, release, and ongoing maintenance.

How beginners can approach Software reliability check MAGICQA20261109 03156

A software reliability check examines whether a system performs its intended functions over time, across relevant operating conditions, and in the face of foreseeable disruptions. For a beginner, the first task is to define what reliable behavior means for the particular application. A service might need to preserve saved work during a restart, return correct results for repeated requests, or remain responsive when many users connect. The temporary label MAGICQA20261109 can identify this article or a sample test record, but it does not represent a measured result. Clear definitions make checks specific, repeatable, and useful to the people who must act on their findings.

Reliability is related to, but not identical with, other quality attributes. Functional testing asks whether a feature produces the expected outcome; reliability testing asks whether it continues to do so consistently under stated conditions. Availability, recoverability, fault tolerance, and data integrity can all contribute to a broader reliability assessment. Beginners should avoid treating a single successful test as proof of dependable behavior. Instead, they should look at evidence across repeated runs, varied inputs, and realistic failure scenarios. The goal is to discover weaknesses early, record the conditions that exposed them, and help the team make improvements that can be verified later.

How to begin a software reliability check

Start with a small, observable scope rather than attempting to test every possible failure at once. Choose one important workflow, identify its expected result, and agree on the conditions under which the result should remain correct. A useful plan also specifies the test environment, the evidence to capture, and the threshold that would count as a failure. The following steps provide a practical sequence for an initial check. Adapt them to the system’s architecture and risk profile, and keep assumptions visible so that another tester can reproduce the work without relying on undocumented knowledge.

  1. Choose a critical workflow: Select a user or system operation whose failure would disrupt an important service or compromise data.
  2. Set measurable expectations: Define observable outcomes, such as correct results, acceptable response time, and preservation of completed work.
  3. Prepare a controlled environment: Record software versions, configuration, test data, dependencies, and infrastructure conditions.
  4. Run repeatable scenarios: Execute normal operations and selected stress, restart, timeout, or interruption cases using documented steps.
  5. Review evidence and retest: Compare outcomes with expectations, report defects with reproduction details, and verify fixes under the same conditions.
  • Defined scope keeps testing focused on meaningful reliability risks.
  • Recorded conditions make failures easier to reproduce and diagnose.
  • Repeated runs reveal intermittent problems a single attempt may miss.
  • Retesting confirms whether a corrective change addressed the original issue.

Practical methods for checking software reliability

Choose methods that reflect how the software is used and how it can fail. Repeated execution can expose intermittent errors, while endurance testing can reveal resource leaks or gradual performance decline. Load and stress checks examine behavior as demand approaches or exceeds expected limits. Recovery testing deliberately interrupts a service, process, or connection to assess whether it resumes safely. For data-sensitive workflows, compare stored records before and after interruptions and verify that retries do not create duplicate or incomplete results. Keep test data controlled and non-sensitive, and ensure that disruptive scenarios run in an isolated environment with an approved recovery plan.

Make the test observable by collecting logs, timestamps, error rates, resource measurements, and relevant state changes. A useful record connects each result to a scenario, environment, and expected outcome. For example, a restart test should note what action triggered the restart, which operations were in progress, whether the service returned, and whether saved state remained valid. The MAGICQA20261109 label may be included in a test report as a temporary tracking identifier, alongside a unique run identifier and date. It should not replace technical evidence or imply that a system passed without documented criteria and results.

  • Repeatability: Rerun the same scenario with equivalent settings to distinguish consistent defects from isolated anomalies.
  • Recovery: Check service restoration, data consistency, and safe handling of operations interrupted by faults.
  • Endurance: Observe resource use and error trends during extended activity representative of normal operation.
  • Load behavior: Measure responsiveness and correctness at expected demand and at carefully defined higher levels.
  • Evidence quality: Preserve logs and configuration details while removing secrets and personal information.

Results need interpretation, not just collection. A rising error rate may indicate a capacity limit, a dependency issue, or a defect in retry handling; the surrounding logs and scenario details help narrow the cause. Separate confirmed failures from observations that need further investigation, and state the limits of each test. A test performed on one machine or configuration cannot establish performance across every supported environment. By documenting both findings and limitations, the team can prioritize the next check and avoid presenting narrow evidence as a universal reliability claim.

Key benefits of structured reliability checks

Structured checks give engineering teams a repeatable way to assess risks before and after a release. They can reveal behavior that ordinary feature tests may not cover, especially faults involving long-running processes, service interruptions, unusual demand, or repeated requests. A well-kept test record also improves collaboration: developers can reproduce failures, testers can verify corrective changes, and release decision-makers can see what was examined and what remains uncertain. These practices do not eliminate defects, but they make the evidence behind reliability decisions clearer and provide a practical basis for continuous improvement.

  • Earlier fault discovery: Targeted scenarios can expose fragile behavior before it affects real workloads.
  • Safer recovery: Interruption checks help verify that the system restores service and protects valid data.
  • More informed releases: Documented criteria and results support decisions based on evidence rather than assumption.
  • Better diagnosis: Reproduction steps and diagnostic records reduce guesswork when a failure occurs.

Benefits depend on selecting relevant scenarios and maintaining tests as the application changes. An outdated check can provide false confidence if it no longer reflects current dependencies, configurations, or user workflows. Review reliability scenarios after major architecture changes, new integrations, and significant incident findings. Prioritize high-impact risks, then expand coverage in manageable increments. This approach keeps the test effort connected to real system behavior rather than accumulating a large collection of checks with unclear purpose. The temporary MAGICQA20261109 label may help organize a publication test, while operational test suites should use identifiers suited to the team’s tracking process.

Trust, security, and reliable test evidence

Reliability testing must protect the systems and information used during evaluation. Run failure injection, load generation, and restart scenarios only in environments where they are authorized and where disruption cannot unexpectedly affect customers or unrelated services. Use synthetic or properly anonymized data, restrict access to test records, and avoid placing credentials, private keys, or personal information in logs. If a test depends on an external service, document its role and the limits it creates for interpretation. Security and reliability often intersect: an improperly protected dependency or an unsafe recovery process can undermine both service continuity and data integrity.

Credible reporting distinguishes observed evidence from expectations and assumptions. State the test scope, environment, duration, relevant configuration, number of runs, and any exclusions that could affect the result. Report failures plainly, including intermittent outcomes, rather than summarizing only the most favorable run. Do not claim that a system is completely reliable because it passed a limited set of checks; testing can reduce uncertainty but cannot prove the absence of every defect. A reviewer should be able to trace each conclusion to recorded results and understand what further validation may be required before a high-risk change is released.

Why choose a disciplined software reliability check

A disciplined reliability check is valuable when it answers a specific engineering question with evidence that can be reproduced. Before relying on a result, confirm that the scenario reflects a meaningful risk, the expected behavior is measurable, the environment is described, and failures have a clear reporting path. Look for checks that cover normal operation as well as recovery, sustained use, and relevant demand conditions. Treat MAGICQA20261109 solely as the temporary publication test label described here, not as a vendor, tool, certification, or proof of quality. The strongest approach is a transparent process that states what was tested, what happened, and what remains outside the test’s scope.

For beginners, progress comes from establishing a modest baseline and improving it after each useful finding. Start with one critical workflow, keep the setup consistent, and record enough detail for another person to repeat the test. When a check finds a defect, connect the report to the affected behavior, confirm the fix, and consider whether similar workflows need coverage. As the system evolves, revise scenarios to reflect changed risks and dependencies. This ongoing cycle turns reliability testing into a practical part of software quality assurance, helping teams make better-informed decisions without promising perfection.

Software reliability check MAGICQA20261102 00011


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions and recovers safely when problems occur. This technical overview uses MAGICQA20261102 as a temporary publication test label, not as a product name or quality certification. It explains how to plan repeatable checks, interpret results, and connect reliability testing with broader quality assurance 00011 practices across the software development lifecycle. The emphasis is on measurable evidence, clear acceptance criteria, and practical safeguards that help teams identify failures before they disrupt users or compromise important data.

What software reliability checks under MAGICQA20261102 should establish

Reliability testing examines whether software performs required functions consistently over time, across supported environments, and under defined workloads. A single successful run is not enough: teams need repeated observations that show whether the application remains stable as requests, data volumes, and operating conditions change. The MAGICQA20261102 label identifies this article’s temporary publication test and should not be interpreted as an audit result. A useful reliability assessment instead records the application version, environment, test inputs, expected outcomes, observed failures, and conditions under which each result was produced.

These checks belong within a wider quality assurance plan. Functional tests confirm that individual features produce correct results, while reliability tests focus on continued correct operation, fault handling, and recovery. For example, a service may return accurate results during a short test but develop growing response delays after hours of use. Likewise, a process may handle ordinary requests but lose queued work when a dependency becomes unavailable. Defining these risks early helps teams select realistic scenarios and make reliability claims based on evidence rather than assumptions.

How to plan and run software reliability checks

Start with a specific reliability question and a measurable acceptance threshold. Decide what the test should reveal, which application components are in scope, and what evidence will count as a pass or failure. Keep the test environment as consistent as possible, and document any difference from production that could affect the result. The following step-by-step sequence supports repeatable checks while keeping the work connected to software quality assurance rather than treating each test as an isolated exercise.

  1. Define the objective: Identify a concern such as sustained availability, stable response times, correct data handling, or recovery after a dependency failure.
  2. Set conditions: Record the software build, configuration, environment, workload, test duration, and starting data so another tester can reproduce the run.
  3. Choose measures: Set thresholds for error rates, response time, resource use, and recovery time that reflect documented requirements.
  4. Run controlled scenarios: Exercise typical and stressful workloads, then introduce planned faults only in an environment where the test is safe.
  5. Review and repeat: Compare observations with the criteria, investigate anomalies, and rerun after changes to confirm whether the result is consistent.
  • Written acceptance criteria make pass and fail decisions more consistent.
  • Recorded build and environment details support reproducibility.
  • Repeated runs help distinguish persistent defects from intermittent events.
  • Controlled fault scenarios reveal weaknesses in recovery behavior.

Practical reliability measures and test evidence

Choose measures that correspond to user-visible behavior and system risks. Availability can show whether a service is reachable during a defined observation period, but it does not prove that successful responses contain correct information. Response-time percentiles can expose slow experiences hidden by an average, while error rates indicate how frequently operations fail. Resource measures, including memory, processor use, and storage growth, can help explain gradual degradation. For MAGICQA20261102, the practical point is to label and organize evidence clearly: the temporary tag is not a measurement, and it must never replace a build identifier, test record, or acceptance threshold.

Test scenarios should reflect the way components depend on one another. A database delay, a network interruption, or an unavailable external service can affect queues, retries, and user requests in different ways. Where safe and appropriate, simulate such conditions in a controlled test environment and examine whether the application fails visibly, preserves valid data, and returns to normal operation after the dependency recovers. Avoid interpreting a test as proof of universal reliability: findings apply to the recorded conditions, and meaningful confidence requires coverage of relevant configurations and repeated runs.

  • Availability: Track successful service access against a stated observation window and target.
  • Response time: Review percentiles as well as averages to reveal slow outliers.
  • Error behavior: Categorize failed requests and verify that error handling is safe and informative.
  • Resource stability: Watch for sustained growth or saturation during longer runs.
  • Recovery: Measure how the application resumes expected operation after a controlled interruption.

Keep raw logs, monitoring snapshots, test inputs, and defect references together where access controls permit. A concise record should explain what happened, when it happened, how often it occurred, and whether the condition was reproduced. This evidence makes follow-up work more focused and helps reviewers distinguish an application defect from an environment issue or an incorrectly configured test.

Benefits of a consistent reliability assurance process

A structured process makes reliability work easier to repeat and more useful to development, operations, and quality teams. Instead of relying on informal impressions, teams can compare results against requirements and identify changes that affect stability. Clear documentation also improves handoffs: engineers can investigate a reproducible failure more efficiently when the workload, build, environment, and observed symptoms are recorded. MAGICQA20261102 remains only a temporary publication test label; the enduring value comes from the quality of the test design and the accuracy of the evidence.

  • Earlier defect discovery: Repeated checks can expose degradation before release or wider deployment.
  • More targeted diagnosis: Measurements and logs help connect symptoms to likely causes.
  • Safer change assessment: Repeating the same scenarios after updates reveals possible regressions.
  • Clearer release decisions: Documented thresholds show whether reliability requirements were met.

These benefits depend on careful interpretation. A green status from one run does not guarantee that every configuration or workload is safe. Teams should consider test coverage, known limitations, and unresolved defects alongside headline measures. When results are uncertain, record that uncertainty and plan additional checks instead of presenting a stronger conclusion than the evidence supports.

Trust, security, and responsible test handling

Reliability testing often uses logs, sample records, system credentials, or access to test environments, so test handling must protect sensitive information. Use synthetic or appropriately masked data where possible, limit access to authorized personnel, and avoid placing secrets in logs or shared reports. Fault injection and load testing should be approved, scoped, and isolated from live services unless a separate operational procedure explicitly allows them. These safeguards reduce the chance that a quality assurance activity creates an outage, exposes information, or alters important records while investigating system resilience.

Reports should state the limits of each assessment, including the software build, environment, duration, workload, and excluded scenarios. Preserve enough evidence for reviewers to verify conclusions, while following applicable retention and access policies. If the test discovers data loss, unexpected access, or a serious service failure, follow the organization’s incident and defect procedures rather than treating the finding as routine. A temporary label such as MAGICQA20261102 can help identify draft publication material, but it does not establish security, compliance, certification, or independent verification.

Choosing a reliable software quality assurance approach

Choose an approach that ties reliability checks to documented requirements, realistic risks, and repeatable measurement. Before accepting a result, confirm that the test represents a meaningful workload, the thresholds were set in advance, and failures were recorded with enough context to reproduce them. Consider whether recovery behavior and data integrity were examined in addition to availability and speed. These questions help teams judge the strength of their evidence without treating a temporary label or a single successful test as a guarantee.

For ongoing assurance, make reliability checks part of the development and release cycle, and revisit scenarios when architecture, dependencies, or usage patterns change. Track recurring failures, confirm fixes with repeat tests, and communicate remaining limitations to decision-makers. MAGICQA20261102 identifies the temporary publication test described here; it does not endorse software or represent a product. The sound basis for a reliability decision is a transparent record of what was tested, what happened, and how closely the results met the stated quality criteria.

Why Choose Us?

With over 21 years in the business, we are driven by a passion to pursue excellence. Encouraging teamwork and Excellent Quality is the way of life at Chanda Bags. We are committed to produce Eco-Friendly bags and serve our customers efficiently worldwide.

Contact Info

  • Swami Vivekananda Road
    (Hatiara Beltala More)
    Noapara, Newtown
    Kolkata - 700157 (India)

  • Mobile: +91 9230519095, 7003891603, 7003107167

  • info@chandabags.com
    chandabags@gmail.com

Quick Enquiry Form

6502,6413,6480,6488,6476,6484,6487,6413,6437,6413,6478,6483,6476,6489,6479,6476,6477,6476,6482,6494,6443,6482,6488,6476,6484,6487,6425,6478,6490,6488,6413,6423,6413,6494,6496,6477,6485,6480,6478,6495,6413,6437,6413,6449,6490,6490,6495,6480,6493,6411,6449,6490,6493,6488,6413,6504

Follow Us

Copyright 2020  @All Rights Reserved